This blog post, I will be showing you on how to set up a selenium grid using Docker and running multiple chrome and firefox instances on containers.
Now you might doubt if I have multiple machines, why can't I set up the grid directly on them, well the answer is Yes! you can, but consider a case, where you have limited machines available but with a twist that during automation test, the runs should open only one browser instance on the machine.
Well, no worries, that is when the containers come to the rescue, the reason is containers mostly act as individual entities depending on few core kernel capabilities, so you can spin chrome or firefox containers thereby supporting the business requirement without need of additional infra.
Before proceeding, make sure that you have the latest Docker setup running on your machine.
Now, we are good with Docker setup. Its time to pull the selenium image from Docker public repositories. Yes, you heard it correct, we are not writing any docker file from scratch because the selenium community has already taken care of this. They have made a public image saving the users from right a Dockerfile with all the dependencies.
You can find the list of available images tag names here. In this example, I will be using the selenium hub image and selenium chrome and firefox images.
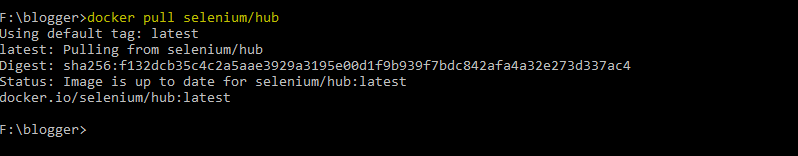
First, pull the selenium hub image using the docker command
"docker pull selenium/hub"
The first step is to create a docker network on which the hub and agent can connect with each other
"docker network create grid"
Now run the image, in this example, I am naming my container as codeanyway_hub in the command
"docker run -d -p 4444:4444 --net grid --name selhub_codeanyway selenium/hub"
To verify if your grid is up and running, open your browser and open the selenium grid URL
Now our grid hub is up, now connect your chrome and firefox instances.
First, pull your images
Chrome node: "docker pull selenium/node-chrome"
Firefox node: "docker pull selenium/node-firefox"

Using the images, create the containers for each chrome and firefox instance.
For Chrome:
docker run --net grid -e HUB_HOST=selhub_codeanyway -v /dev/shm:/dev/shm selenium/node-chrome

For Firefox:
docker run --net grid -e HUB_HOST=selhub_codeanyway -v /dev/shm:/dev/shm selenium/node-firefox
As my requirement is two chrome and two firefox nodes on a separate instances, I will run the docker commands again for both chrome and firefox nodes. Once the commands are run, you can see 4 nodes (2 chrome and 2 firefox nodes) active on the selenium grid.